Netflix benchmark baselines — how to reproduce them
To re-run the Netflix benchmark suite, follow Running the suite and compare against the recorded snapshot with Diffing a fresh run. This page documents the harness behind testdata/netflix_benchmark_results.json (the fork's recorded per-backend score and throughput snapshot for the three Netflix fixtures) and, at the end, what the last re-run measured.
This is not the Netflix golden-data gate
The golden gate is the Python assertAlmostEqual suite invoked by make test-netflix-golden (AGENTS.md section 8); its assertions are never edited. testdata/netflix_benchmark_results.json is fork-added data governed by the /regen-snapshots rule and by ADR-1192.
Status of the 2026-09-06 blockers
ADR-1192 gated regenerating the snapshot on two GPU defects found by the 2026-09-06 re-run. Both are closed in docs/state.md: the --threads abort as T-GPU-CLI-THREADS-CTX-SYNC-2026-09-06 and the non-deterministic libvmaf_cuda filter as T-CUDA-FFMPEG-FILTER-NONDETERMINISM-2026-09-06 (ADR-1197, ADR-1199). The snapshot itself was last written on 2026-05-02 and has not been regenerated; rewriting it still needs the /regen-snapshots justification.
Which harness writes which file
There are six benchmark scripts under testdata/, and the first three are easy to confuse:
| Script | Path exercised | Fixtures | Writes |
|---|---|---|---|
testdata/benchmark_netflix.py | FFmpeg libvmaf / libvmaf_cuda / libvmaf_sycl filters | src01 576x324 (48f), checkerboard 1080p mild + heavy (3f each) | testdata/netflix_benchmark_results.json |
testdata/bench_all.sh | the vmaf CLI binary | src01 576x324, src01 1080p 5f, BBB 4K 200f | nothing (prints a report) |
testdata/bench_perf.py | FFmpeg filters, portable/parameterised | BBB pairs | testdata/perf_benchmark_results.json (historical) |
testdata/bench_backends.py | the vmaf CLI, one exclusive --backend per run | per-backend cells; warmup then --runs repetitions, median with min/max and load average | JSON in the perf_benchmark_results.json key shape |
testdata/bench_quick.py | the vmaf CLI | 48-frame pairs from 576x324 to 3840x2160 found under testdata/, 3 runs each, best fps | stdout |
testdata/bench_upstream_ab.py | fork CPU build against upstream Netflix/vmaf at a pinned commit | speedup plus score parity (scripts/dev/upstream_parity.py, ADR-1487) | stdout; --json FILE writes the full result document |
testdata/compare_combined.py compares scores_cpu_*.json against scores_sycl_a380_*.json. It does not read netflix_benchmark_results.json, so it cannot be used to diff a fresh benchmark_netflix.py run against the recorded snapshot — compare the JSON directly (see Diffing a fresh run).
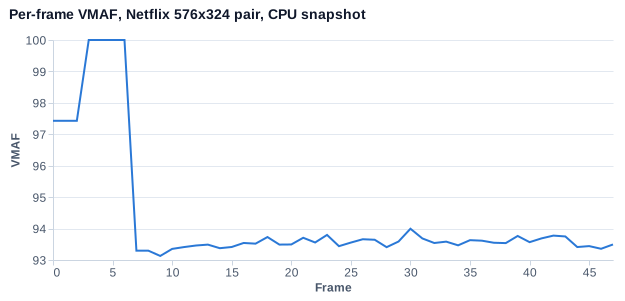
Source: testdata/scores_cpu_576.json and the three testdata/scores_sycl_*_576.json snapshots. Hover a frame for every snapshot's value.
Data table
| Frame | CPU | SYCL, Arc A380 | SYCL, Arc B580 | SYCL, UHD Graphics 770 |
|---|---|---|---|---|
| 0 | 97.428043 | 97.428043 | 97.428043 | 97.428043 |
| 1 | 97.428043 | 97.428043 | 97.428043 | 97.428043 |
| 2 | 97.428043 | 97.428043 | 97.428043 | 97.428043 |
| 3 | 100.000000 | 100.000000 | 100.000000 | 100.000000 |
| 4 | 100.000000 | 100.000000 | 100.000000 | 100.000000 |
| 5 | 100.000000 | 100.000000 | 100.000000 | 100.000000 |
| 6 | 100.000000 | 100.000000 | 100.000000 | 100.000000 |
| 7 | 93.297156 | 93.297156 | 93.297109 | 93.297109 |
| 8 | 93.297029 | 93.297029 | 93.297009 | 93.297009 |
| 9 | 93.129024 | 93.129024 | 93.129006 | 93.129006 |
| 10 | 93.353280 | 93.353280 | 93.353257 | 93.353257 |
| 11 | 93.411692 | 93.411692 | 93.411658 | 93.411658 |
| 12 | 93.461133 | 93.461133 | 93.461083 | 93.461083 |
| 13 | 93.489398 | 93.489398 | 93.489312 | 93.489312 |
| 14 | 93.375616 | 93.375616 | 93.375507 | 93.375507 |
| 15 | 93.413759 | 93.413759 | 93.413685 | 93.413685 |
| 16 | 93.541790 | 93.541790 | 93.541692 | 93.541692 |
| 17 | 93.520327 | 93.520327 | 93.520276 | 93.520276 |
| 18 | 93.730405 | 93.730405 | 93.730280 | 93.730280 |
| 19 | 93.490447 | 93.490447 | 93.490371 | 93.490371 |
| 20 | 93.494035 | 93.494035 | 93.493978 | 93.493978 |
| 21 | 93.707219 | 93.707219 | 93.707165 | 93.707165 |
| 22 | 93.557214 | 93.557214 | 93.557192 | 93.557192 |
| 23 | 93.797764 | 93.797764 | 93.797730 | 93.797730 |
| 24 | 93.440080 | 93.440080 | 93.440090 | 93.440090 |
| 25 | 93.554528 | 93.554528 | 93.554496 | 93.554496 |
| 26 | 93.660619 | 93.660619 | 93.660582 | 93.660582 |
| 27 | 93.644348 | 93.644348 | 93.644297 | 93.644297 |
| 28 | 93.408297 | 93.408297 | 93.408243 | 93.408243 |
| 29 | 93.587686 | 93.587686 | 93.587605 | 93.587605 |
| 30 | 93.994964 | 93.994964 | 93.994934 | 93.994934 |
| 31 | 93.686070 | 93.686070 | 93.686003 | 93.686003 |
| 32 | 93.540831 | 93.540831 | 93.540768 | 93.540768 |
| 33 | 93.584258 | 93.584258 | 93.584213 | 93.584213 |
| 34 | 93.466789 | 93.466789 | 93.466759 | 93.466759 |
| 35 | 93.631166 | 93.631166 | 93.631109 | 93.631109 |
| 36 | 93.614717 | 93.614717 | 93.614653 | 93.614653 |
| 37 | 93.548852 | 93.548852 | 93.548771 | 93.548771 |
| 38 | 93.537819 | 93.537819 | 93.537802 | 93.537802 |
| 39 | 93.764782 | 93.764782 | 93.764741 | 93.764741 |
| 40 | 93.567850 | 93.567850 | 93.567787 | 93.567787 |
| 41 | 93.687888 | 93.687888 | 93.687850 | 93.687850 |
| 42 | 93.776223 | 93.776223 | 93.776174 | 93.776174 |
| 43 | 93.749125 | 93.749125 | 93.749094 | 93.749094 |
| 44 | 93.412491 | 93.412491 | 93.412458 | 93.412458 |
| 45 | 93.442175 | 93.442175 | 93.442142 | 93.442142 |
| 46 | 93.356980 | 93.356980 | 93.356953 | 93.356953 |
| 47 | 93.494516 | 93.494516 | 93.494526 | 93.494526 |
Prerequisites
benchmark_netflix.py drives an FFmpeg binary that links the fork's libvmaf and carries all three filters. The supported way to get one is the vmaf-dev-mcp container (dev-mcp.md), which ships FFmpeg with libvmaf, libvmaf_cuda and libvmaf_sycl already wired up.
The YUV fixtures live in python/test/resource/yuv/ and are gitignored, so they exist only in a full checkout. Point VMAF_YUVDIR at that checkout when running from a worktree.
Two environment variables select host-specific inputs (both defaults are host-specific and are expected to be set):
| Variable | Meaning |
|---|---|
VMAF_FFMPEG | FFmpeg binary to drive. |
VMAF_SYCL_RENDER_NODE | VA-API render node for the SYCL/QSV import path (default /dev/dri/renderD128); see Picking the SYCL render node. |
Running the suite
To measure current libvmaf rather than the one baked into the image, build the library out-of-source inside the container and put it ahead of the installed one on LD_LIBRARY_PATH. FFmpeg resolves libvmaf.so.3 at load time, so no FFmpeg rebuild is needed as long as the public headers under core/include/libvmaf/ have not changed shape.
-
Build current master's libvmaf inside the container, out of source.
docker exec vmaf-dev-mcp bash -lc ' set +u; source /opt/intel/oneapi/setvars.sh >/dev/null 2>&1; set -u CC=icx CXX=icpx meson setup /tmp/bench-build /workspace/core \ -Denable_cuda=true -Denable_sycl=true \ -Denable_hip=false -Denable_metal=disabled -Denable_dnn=disabled \ -Denable_mcp=false -Denable_tests=false \ --buildtype=release -Db_lto=false -Dc_args=-march=native nice -n 10 ninja -C /tmp/bench-build -j 4' -
Run the suite against it.
docker exec vmaf-dev-mcp bash -lc '
  set +u; source /opt/intel/oneapi/setvars.sh >/dev/null 2>&1; set -u
  export LD_LIBRARY_PATH=/tmp/bench-build/src:$LD_LIBRARY_PATH
  export VMAF_FFMPEG=/usr/local/bin/ffmpeg
  export VMAF_YUVDIR=/workspace/python/test/resource/yuv
  export VMAF_SYCL_RENDER_NODE=$(ls /dev/dri/renderD*)   # see below
  mkdir -p /tmp/benchrun && cp /workspace/testdata/benchmark_netflix.py /tmp/benchrun/
  cd /tmp/benchrun && python3 benchmark_netflix.py'
The script writes its output JSON next to itself, so running the copy in /tmp/benchrun keeps the tracked snapshot untouched. That is deliberate: overwriting testdata/netflix_benchmark_results.json requires the /regen-snapshots justification.
Picking the SYCL render node
benchmark_netflix.py imports frames onto the Intel GPU through QSV/VA-API, so it needs the render node that the iHD driver claims. Node numbering is not stable across hosts or across PCI re-enumeration, so find the right node before running:
docker exec vmaf-dev-mcp bash -lc \
  'for n in /dev/dri/renderD*; do echo "== $n"; vainfo --display drm --device $n 2>&1 | grep -m1 "Driver version"; done'
Pick the node whose driver line reads Intel iHD driver, and pass it as VMAF_SYCL_RENDER_NODE. The script reads only that environment variable (testdata/benchmark_netflix.py); it has no command-line option for it.
Example of unstable numbering
On the ryzen-4090-arc bench host the Arc A380 moved from renderD130 to renderD129, and renderD130 became the AMD iGPU (radeonsi). A run against it fails with DRM_IOCTL_VERSION, unsupported drm device by media driver: amdg.
Diffing a fresh run
python3 - <<'PY'
import json
rec = json.load(open("testdata/netflix_benchmark_results.json"))
new = json.load(open("/tmp/benchrun/netflix_benchmark_results.json"))
for fixture in rec:
    for backend in rec[fixture]:
        r, n = rec[fixture][backend], new.get(fixture, {}).get(backend)
        if not n or "frames" not in n:
            print(f"{fixture:22s} {backend:5s} MISSING in fresh run"); continue
        md = max(abs(a - b) for a, b in zip(r["frames"], n["frames"]))
        print(f"{fixture:22s} {backend:5s} pooled {r['pooled']:.6f} -> {n['pooled']:.6f} "
              f"(delta {n['pooled']-r['pooled']:+.2e}, max per-frame {md:.2e})")
PY
Any non-zero score delta is a correctness finding: open a docs/state.md row, do not regenerate the snapshot. A throughput delta is a performance observation and never justifies a rewrite on its own.
History
Re-run of 2026-09-06, commit cd52f2670
This is a dated measurement, kept as the record of how far the snapshot had drifted. Toolchain versions have moved since (see build-config.env).
Host and method
| Item | Value |
|---|---|
| Host | ryzen-4090-arc: AMD Ryzen 9 9950X3D (32 threads), 60 GiB RAM, Linux 7.2.3-1-cachyos |
| GPUs | NVIDIA RTX 4090 (driver 610.57.04), Intel Arc A380 |
Toolchain in vmaf-dev-mcp (Ubuntu 26.04) | Intel oneAPI DPC++ 2026.1.1, CUDA 13.3.73, FFmpeg n9.0.1-17-gfde3691 |
| libvmaf build | --buildtype=release -Db_lto=false -Dc_args=-march=native |
| Load | Not idle: 1-minute load average 7-19 throughout, with a container image build and other agent sessions running |
Every figure below is from a command run on that host. Timing figures are medians of 5 repetitions with the min/max spread quoted, and are not a substitute for a quiet-host baseline.
Reading the harness's own PASS/DIFF column
benchmark_netflix.py prints each pooled score against the Netflix golden value of the pair (src01_576x324 = 76.66783025, the vmaf CLI assertion in python/test/vmafexec_test.py) and tags it OK within 5e-5. The CPU row agrees with it to about 3e-6. Earlier versions of the harness compared against 76.66890519623612, the value the Python harness asserts in python/test/quality_runner_test.py to two places, so the CPU row always read DIFF; that was a wrong reference, not drift. Compare against the snapshot when asking whether master has drifted.
Scores versus the recorded snapshot
CUDA is quoted at its modal value (see the blockers table below).
| Fixture | Backend | Recorded pooled | 2026-09-06 pooled | Pooled delta | Max per-frame delta |
|---|---|---|---|---|---|
src01_576x324 | cpu | 76.667828 | 76.667831 | +2.83e-06 | 1.70e-05 |
src01_576x324 | cuda | 76.668903 | 76.667830 | -1.07e-03 | 2.85e-03 |
src01_576x324 | sycl | 76.669148 | 76.667746 | -1.40e-03 | 1.54e-02 |
checker_1080p_mild | cpu | 35.068672 | 35.068671 | -6.67e-07 | 1.30e-05 |
checker_1080p_mild | cuda | 35.068669 | 35.068667 | -2.33e-06 | 5.00e-06 |
checker_1080p_mild | sycl | 35.068664 | 35.068628 | -3.60e-05 | 3.90e-05 |
checker_1080p_heavy | cpu | 7.985899 | 7.985899 | 0 | 1.00e-06 |
checker_1080p_heavy | cuda | 7.985899 | 7.985899 | 0 | 1.00e-06 |
checker_1080p_heavy | sycl | 7.985899 | 7.985899 | 0 | 0 |
None of these deltas come from the 2026-09-06 GPU merges:
- Rebuild result. Rebuilding
5a080300e(the commit immediately before #1307, #1312 and #1324) with the same flags gives CUDA 76.667830 and SYCL 76.667745 on the 576x324 pair, the same drift versus the recorded snapshot. - CPU delta. The three merges moved CPU per-frame values by up to about 8e-6; the pooled value is unchanged at six decimals.
- Key-set change. The SYCL
frames[].metricskey set shrank from 35 keys to 24. The CUDA key set is 14 on both commits. - Age. The recorded snapshot dates from PR #309 (2026-05-02), so the drift accumulated across four months.
Throughput (FFmpeg filter path, 576x324 48f and 1080p 3f)
Whole-process wall time including FFmpeg start-up, matching how benchmark_netflix.py computes fps. Median of 5, load average 9.6-9.8 during the sweep. These numbers are observations, not a recorded baseline: no throughput baseline is written while the CUDA path was non-deterministic (ADR-1192).
| Fixture | Backend | Wall ms (median) | Wall ms (min-max) | fps (median) |
|---|---|---|---|---|
| src01 576x324, 48f | cpu | 98 | 95-106 | 489.8 |
| src01 576x324, 48f | cuda | 185 | 180-200 | 259.5 |
| src01 576x324, 48f | sycl | 250 | 237-326 | 192.0 |
| checkerboard 1080p, 3f | cpu | 82 | 74-103 | 36.6 |
| checkerboard 1080p, 3f | cuda | 171 | 168-180 | 17.5 |
| checkerboard 1080p, 3f | sycl | 160 | 152-204 | 18.8 |
The CPU-beats-GPU ordering at these sizes is expected: 48 frames of 576x324 and 3 frames of 1080p do not amortise upload and launch cost. See benchmarks.md for the 4K numbers where CUDA dominates.
Blockers found by this run
Two GPU defects were reproduced. Both were confirmed present on 5a080300e as well, so they were pre-existing rather than introduced on 2026-09-06. Both are closed now (see the status note at the top of this page).
| Blocker | docs/state.md id | Status |
|---|---|---|
vmaf --threads N aborts on every GPU backend | T-GPU-CLI-THREADS-CTX-SYNC-2026-09-06 | Closed (ADR-1197) |
The libvmaf_cuda FFmpeg filter is non-deterministic | T-CUDA-FFMPEG-FILTER-NONDETERMINISM-2026-09-06 | Closed (PR #1346, ADR-1199) |
--threads N abort. --gpumask=0 (CUDA) or --sycl_device=0 (SYCL) combined with any --threads value emitted feature "VMAF_integer_feature_motion2_score" cannot be overwritten at index N for every frame, then libvmaf ERROR context could not be synchronized / problem flushing context, and exited 234 with no output file. Dropping --threads made both backends succeed and score correctly (CUDA 76.667830, SYCL 76.667746 on the 576x324 pair, 10/10 runs each).
testdata/bench_all.sh hard-codes --threads 1, so every CUDA and SYCL row it printed on this host before this run was a masked failure, reported as SKIP (... backend likely unavailable) because the script also discarded stderr. It now keeps stderr in $VMAF_BENCH_OUTDIR/<row>.err and prints FAIL (vmaf exited 234: problem flushing context; see ...). Its flag sets also dropped --no_vulkan, which current CLI builds reject as unrecognized (ADR-0726 removed the Vulkan backend); the flag was ignored rather than fatal, so it had gone unnoticed.
Non-deterministic libvmaf_cuda filter. On the 576x324 48-frame pair, 10 of 40 runs on cd52f2670 and 8 of 40 runs on 5a080300e returned a pooled score other than 76.667830. The bad runs differ in one or two individual frames (for example frame 1 = 0.0, or frame 3 = 50.834 where CPU says 81.925763), not in a global offset. CPU (10/10) and SYCL (10/10) through the same FFmpeg build are bit-stable, and CUDA through the vmaf CLI without a thread pool is bit-stable (10/10). The two failure rates are within binomial noise of each other, so the merges neither caused nor worsened it.